AgentLoop
Record agent execution, investigate wasted work, and verify an improvement with your own quality checks.
Trace model and tool calls, review the evidence behind a finding, and compare baseline and candidate executions on the same tasks.
Get a useful trace
python -m pip install agentloop-profiler
agentloop quickstart
agentloop analyze runs/agentloop_quickstart.json --html runs/report.html
Open runs/report.html to inspect the timeline and findings.
This example runs locally with synthetic data.
How AgentLoop fits your workflow
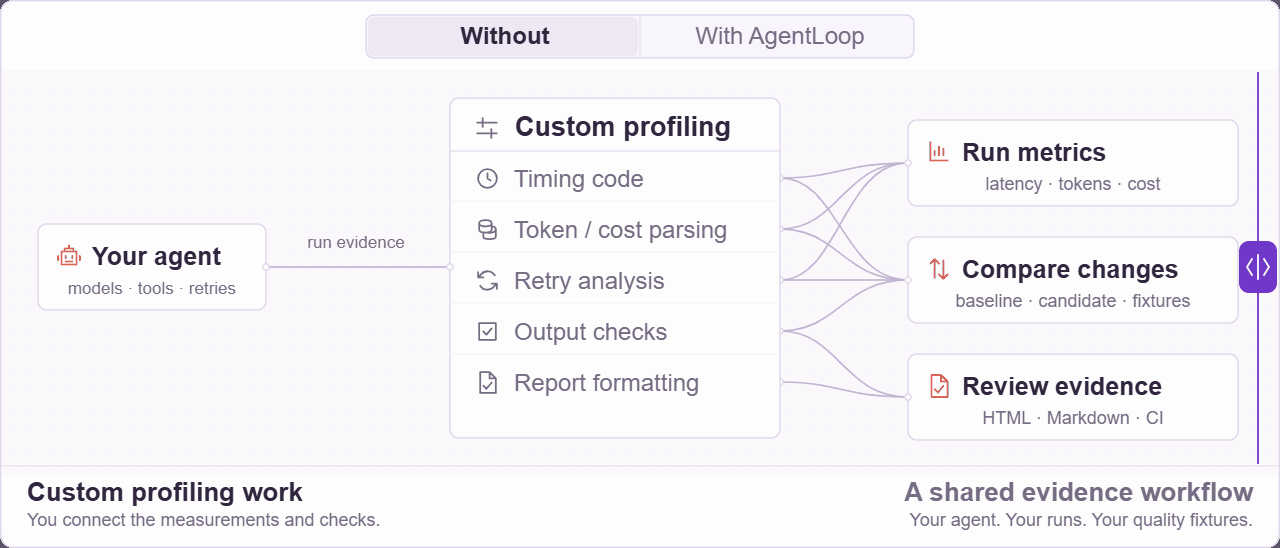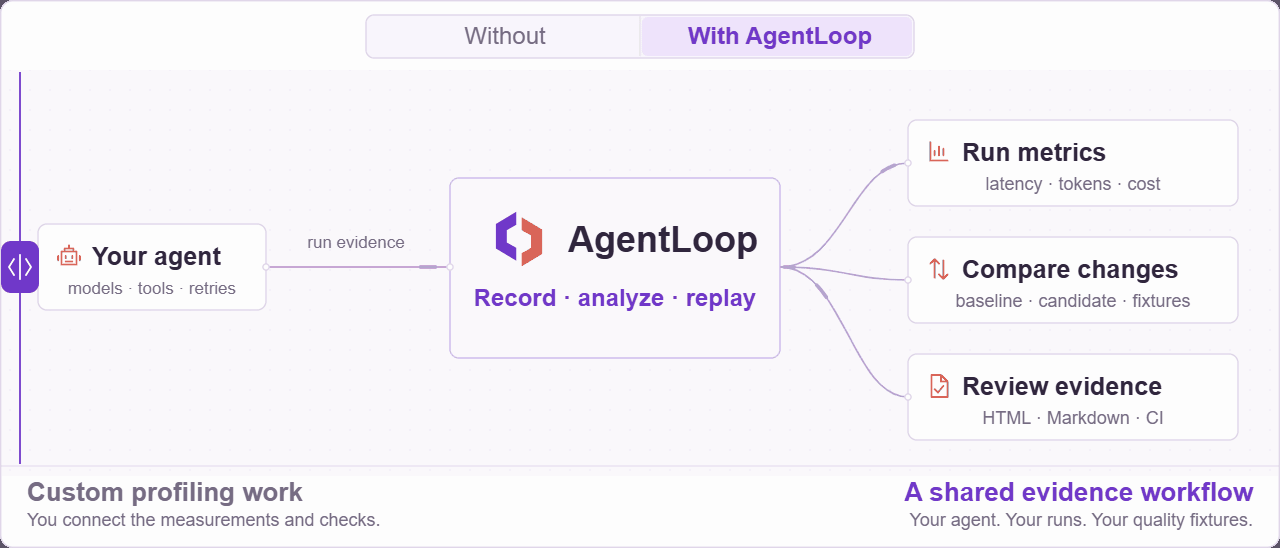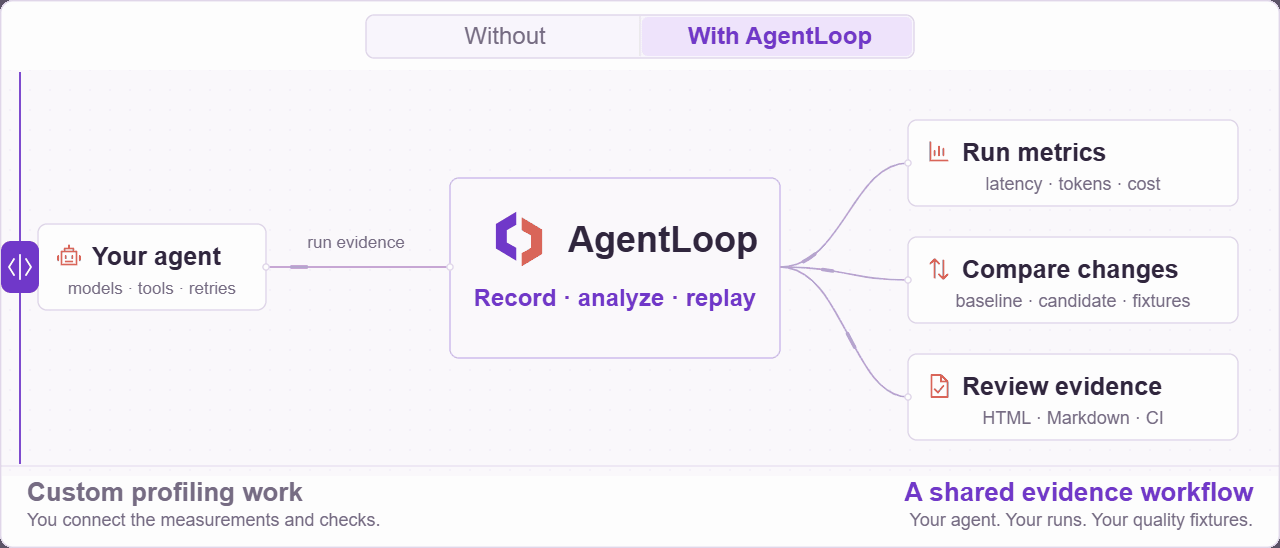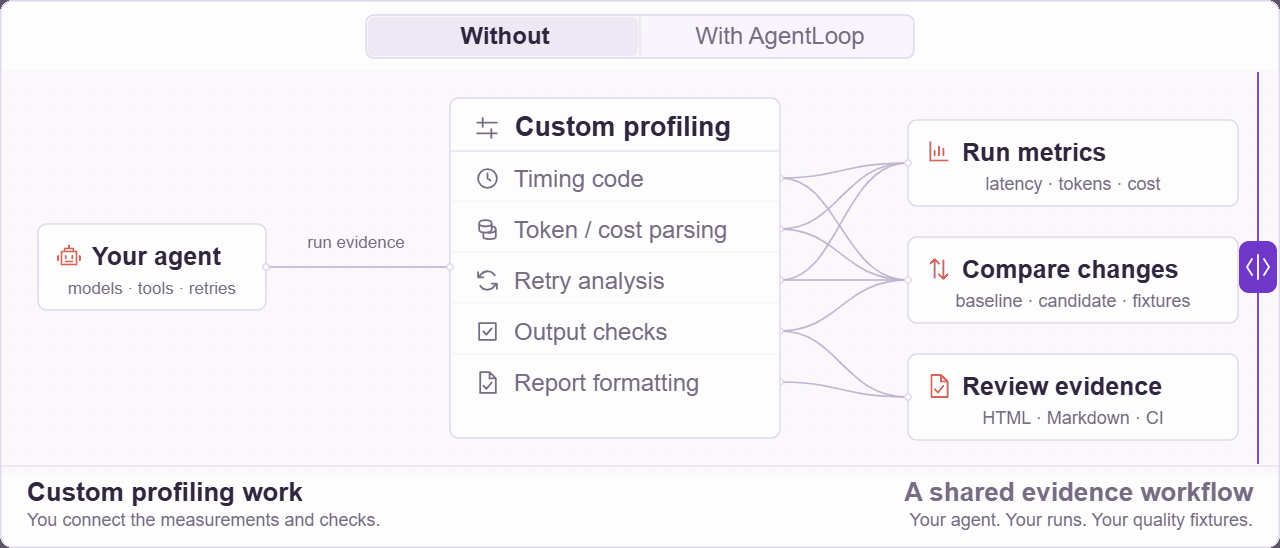
Start with your agent
Guided optimization creates a Python runner and task examples, captures your baseline, and freezes its findings before you apply a change. The comparison checks both answers against independently declared criteria and reports each quality and performance gate.
agentloop improve init --agent my_agent:answer
agentloop improve capture --out baseline -- python agentloop_runner.py
agentloop improve start --baseline baseline/capture.json --out optimization
Read optimization/plan.md, implement one change, then capture the candidate.
The complete guide includes a runnable offline example,
rejection cases, and the before-and-after report. Guided commands require
AgentLoop 0.2.0 or the current source checkout.
Find your next step
-
Instrument Python agents or bring traces from Hermes, LangGraph, Harbor, Omnigent and OpenTelemetry.
-
Inspect supporting spans, assumptions, risk and estimator provenance before choosing a change.
-
Define task-specific checks and inspect rejected candidates, missing usage and incomplete captures.
-
Evaluate supplied application traces and retain the reports and gate decisions.
-
Follow a successful Hermes example and a rejected local-model experiment, with retained measurements and limitations.
-
Record traces in Python or TypeScript and work with the HTTP API.
Read the results in context
Findings distinguish observed execution from inferred assumptions and estimated savings. Candidate comparisons retain measured outcomes, independent quality results and missing evidence. Unknown costs stay unavailable.
The adoption and measurement report describes the remaining work on external developer onboarding, representative workloads and broader performance evidence.